 TypeShade
Domain warping
fbm 출력을 다시 fbm에 넣습니다.
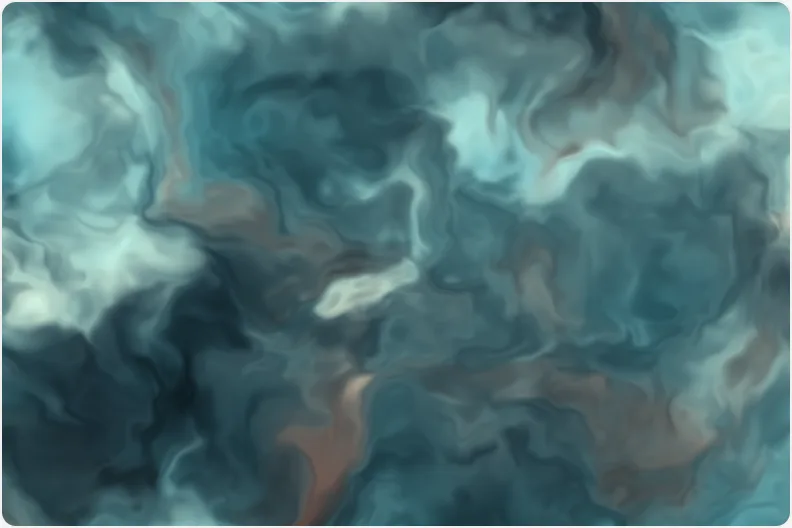
// ═══ typeshade example — domain warping (fbm of fbm of fbm) ═══//// Inigo Quilez's domain-warping construction: instead of colouring by// fbm(p) directly, feed noise its own output — f(p) = fbm(p + w·fbm(p + fbm(p)))// — and the lattice melts into marbled, organic flow. The intermediate warp// vectors q and r double as colour axes. The fbm helper here is a 4-octave// UNROLLED expression (each octave doubles frequency, halves amplitude), so// it stays a pure value function. WGSL (WebGPU) + GLSL ES 3.00 (WebGL2).
import {  fn,  module,  vec2,  vec3,  vec4,  floor,  fract,  mix,  length,  clamp,  smoothstep,  Let,  f32T,  vec2fT,  u32,  i32,  f32,  u32T,} from '../src/index.js';import { VsOut, vs, fullscreenUniforms, screenCoords } from './_fullscreen.js';import type { ShaderExample } from './_shared.js';const U = fullscreenUniforms({ warp: f32T });
// An exact integer hash (lowbias32 with xxHash's primes): every target and the CPU oracle// agree on every bit of it. `fract(sin(x) * 43758.5453)` did not, since WGSL bounds `sin`// only to 2^-11 and the multiply puts that error above the fraction (#184).const hash32 = fn('hash32', { x: u32T }, ({ x }) => {  const a = Let(x.bitXor(x.shr(16)).mul(0x85ebca77));  const b = Let(a.bitXor(a.shr(13)).mul(0xc2b2ae3d));  return b.bitXor(b.shr(16));});
// scalar hash of a lattice point → [0,1): 24 bits, which f32 holds exactlyconst hash = fn('hash', { p: vec2fT }, ({ p }) => {  const h = Let(hash32({ x: u32(i32(p.x)).bitXor(hash32({ x: u32(i32(p.y)) })) }));  return f32(h.shr(8)).mul(5.9604644775390625e-8); // 2^-24, exact: WGSL lets `/` round});
// bilinear value noise with smootherstep weightsconst noise = fn('noise', { p: vec2fT }, ({ p }) => {  const i = Let(floor(p));  const f = Let(fract(p));  const u = f.mul(f).mul(vec2(3).sub(f.mul(2)));  return mix(    mix(hash({ p: i }), hash({ p: i.add(vec2(1, 0)) }), u.x),    mix(hash({ p: i.add(vec2(0, 1)) }), hash({ p: i.add(vec2(1, 1)) }), u.x),    u.y,  );});
// 4-octave fbm, unrolled so the helper stays a pure value expressionconst fbm = fn('fbm', { p: vec2fT }, ({ p }) => {  return noise({ p })    .mul(0.5)    .add(noise({ p: p.mul(2.02) }).mul(0.25))    .add(noise({ p: p.mul(4.08) }).mul(0.125))    .add(noise({ p: p.mul(8.2) }).mul(0.0625));});
const fs = fn(  'fs',  { vo: VsOut },  ({ vo }) => {    const t = U.field.time;    const res = U.field.resolution;    const p = screenCoords(vo.uv, res).mul(1.8);    const w = U.field.warp;    // first warp: q = (fbm(p), fbm(p + k₁))    const q = Let(vec2(fbm({ p }), fbm({ p: p.add(vec2(5.2, 1.3)) })));    // second warp: r = (fbm(p + w·q + k₂ + drift), fbm(p + w·q + k₃))    const pq = p.add(q.mul(w));    const r = Let(      vec2(        fbm({ p: pq.add(vec2(1.7, 9.2)).add(vec2(t.mul(0.15), t.mul(0.12))) }),        fbm({ p: pq.add(vec2(8.3, 2.8)) }),      ),    );    // final field    const f = Let(fbm({ p: p.add(r.mul(w)) }));    // colour: base by f², tinted by the warp magnitudes (iq's construction)    const a = mix(vec3(0.09, 0.12, 0.2), vec3(0.85, 0.83, 0.72), clamp(f.mul(f).mul(2.8), 0, 1));    const b = mix(a, vec3(0.2, 0.5, 0.55), clamp(length(q).mul(0.9), 0, 1));    const c = mix(b, vec3(0.66, 0.3, 0.2), clamp(smoothstep(0.4, 1, r.y).mul(0.6), 0, 1));    return vec4(c.mul(f.mul(1.4).add(0.35)), 1);  },  { stage: 'fragment', retAttr: '@location(0)' },);
const domainWarpModule = module({  structs: [U.struct, VsOut.decl],  bindings: [U.binding],  funcs: [vs, fs],});
export const domainWarp: ShaderExample = {  id: 'domain-warp',  title: 'Domain warping',  blurb:    'fbm fed its own output — f(p) = fbm(p + w·fbm(p + fbm(p))) — melts lattice noise into marbled organic flow; the intermediate warp vectors double as colour axes. Warp strength is live.',  category: 'generic',  file: 'domain-warp.ts',  module: domainWarpModule,  renderable: true,  controls: {    time: { kind: 'time' },    resolution: { kind: 'resolution' },    warp: { kind: 'slider', label: 'Warp', min: 0, max: 4, step: 0.1, value: 2.4 },  },};
struct Uniforms { time: f32, resolution: vec2<f32>, warp: f32,}
struct VsOut { @builtin(position) pos: vec4<f32>, @location(0) uv: vec2<f32>,}
@group(0) @binding(0) var<uniform> U: Uniforms;
fn hash32(x: u32) -> u32 { let _v0 = ((x ^ (x >> 16u)) * 2246822519u); let _v1 = ((_v0 ^ (_v0 >> 13u)) * 3266489917u); return (_v1 ^ (_v1 >> 16u));}
fn hash(p: vec2<f32>) -> f32 { let _v0 = hash32((u32(i32(p.x)) ^ hash32(u32(i32(p.y))))); return (f32((_v0 >> 8u)) * 5.960464477539063e-8);}
fn noise(p: vec2<f32>) -> f32 { let _v0 = floor(p); let _v1 = fract(p); let _cse0 = vec2<f32>(3.0); let _gv0 = ((_v1 * _v1) * (_cse0 - (_v1 * 2.0))); let _lc0 = _gv0.x; return mix(mix(hash(_v0), hash((_v0 + vec2<f32>(1.0, 0.0))), _lc0), mix(hash((_v0 + vec2<f32>(0.0, 1.0))), hash((_v0 + vec2<f32>(1.0, 1.0))), _lc0), _gv0.y);}
fn fbm(p: vec2<f32>) -> f32 { return ((((noise(p) * 0.5) + (noise((p * 2.02)) * 0.25)) + (noise((p * 4.08)) * 0.125)) + (noise((p * 8.2)) * 0.0625));}
@vertexfn vs(@builtin(vertex_index) vi: u32) -> VsOut { let _cse0 = ((f32((vi & 1u)) * 4.0) - 1.0); let _cse1 = ((f32((vi >> 1u)) * 4.0) - 1.0); return VsOut(vec4<f32>(_cse0, _cse1, 0.0, 1.0), vec2<f32>(((_cse0 * 0.5) + 0.5), ((_cse1 * 0.5) + 0.5)));}
@fragmentfn fs(vo: VsOut) -> @location(0) vec4<f32> { let _cse0 = (vec2<f32>((((vo.uv.x * 2.0) - 1.0) * (U.resolution.x / U.resolution.y)), ((vo.uv.y * 2.0) - 1.0)) * 1.8); let _v0 = vec2<f32>(fbm(_cse0), fbm((_cse0 + vec2<f32>(5.2, 1.3)))); let _lc0 = (_cse0 + (_v0 * U.warp)); let _v1 = vec2<f32>(fbm(((_lc0 + vec2<f32>(1.7, 9.2)) + vec2<f32>((U.time * 0.15), (U.time * 0.12)))), fbm((_lc0 + vec2<f32>(8.3, 2.8)))); let _v2 = fbm((_cse0 + (_v1 * U.warp))); return vec4<f32>((mix(mix(mix(vec3<f32>(0.09, 0.12, 0.2), vec3<f32>(0.85, 0.83, 0.72), clamp(((_v2 * _v2) * 2.8), 0.0, 1.0)), vec3<f32>(0.2, 0.5, 0.55), clamp((length(_v0) * 0.9), 0.0, 1.0)), vec3<f32>(0.66, 0.3, 0.2), clamp((smoothstep(0.4, 1.0, _v1.y) * 0.6), 0.0, 1.0)) * ((_v2 * 1.4) + 0.35)), 1.0);}#version 300 esprecision highp float;precision highp int;
out vec2 uv;
void main() { uint vi = uint(gl_VertexID); float _cse0 = ((float((vi & 1u)) * 4.0) - 1.0); float _cse1 = ((float((vi >> 1u)) * 4.0) - 1.0); gl_Position = vec4(_cse0, _cse1, 0.0, 1.0); uv = vec2(((_cse0 * 0.5) + 0.5), ((_cse1 * 0.5) + 0.5));}#version 300 esprecision highp float;precision highp int;
layout(std140) uniform Uniforms { float time; vec2 resolution; float warp;} U;int _f2i(float x) { return int(mix(clamp(x, -2147483648.0, 2147483520.0), 0.0, isnan(x)));}uint hash32(uint x) { uint _v0 = ((x ^ (x >> 16u)) * 2246822519u); uint _v1 = ((_v0 ^ (_v0 >> 13u)) * 3266489917u); return (_v1 ^ (_v1 >> 16u));}
float hash(vec2 p) { uint _v0 = hash32((uint(_f2i(p.x)) ^ hash32(uint(_f2i(p.y))))); return (float((_v0 >> 8u)) * 5.960464477539063e-8);}
float noise(vec2 p) { vec2 _v0 = floor(p); vec2 _v1 = fract(p); vec2 _cse0 = vec2(3.0); vec2 _gv0 = ((_v1 * _v1) * (_cse0 - (_v1 * 2.0))); float _lc0 = _gv0.x; return mix(mix(hash(_v0), hash((_v0 + vec2(1.0, 0.0))), _lc0), mix(hash((_v0 + vec2(0.0, 1.0))), hash((_v0 + vec2(1.0, 1.0))), _lc0), _gv0.y);}
float fbm(vec2 p) { return ((((noise(p) * 0.5) + (noise((p * 2.02)) * 0.25)) + (noise((p * 4.08)) * 0.125)) + (noise((p * 8.2)) * 0.0625));}in vec2 uv;layout(location = 0) out vec4 _ret;
void main() { vec2 _cse0 = (vec2((((uv.x * 2.0) - 1.0) * (U.resolution.x / U.resolution.y)), ((uv.y * 2.0) - 1.0)) * 1.8); vec2 _v0 = vec2(fbm(_cse0), fbm((_cse0 + vec2(5.2, 1.3)))); vec2 _lc0 = (_cse0 + (_v0 * U.warp)); vec2 _v1 = vec2(fbm(((_lc0 + vec2(1.7, 9.2)) + vec2((U.time * 0.15), (U.time * 0.12)))), fbm((_lc0 + vec2(8.3, 2.8)))); float _v2 = fbm((_cse0 + (_v1 * U.warp))); _ret = vec4((mix(mix(mix(vec3(0.09, 0.12, 0.2), vec3(0.85, 0.83, 0.72), clamp(((_v2 * _v2) * 2.8), 0.0, 1.0)), vec3(0.2, 0.5, 0.55), clamp((length(_v0) * 0.9), 0.0, 1.0)), vec3(0.66, 0.3, 0.2), clamp((smoothstep(0.4, 1.0, _v1.y) * 0.6), 0.0, 1.0)) * ((_v2 * 1.4) + 0.35)), 1.0);}Domain warping. 빌드할 때 그린 화면입니다.
WGSL과 GLSL 탭은 커밋 c66579bf의 컴파일러가 직접 낸 출력입니다. 컴파일러의 출력 검사가 구워 둔 골든 파일에서 그대로 읽어 왔습니다(emit-goldens.test.ts).
이 예제는 fn() 빌더 API로 작성해서 Playground의 편집기가 받지 않습니다.